A single equipment failure can disrupt an entire production schedule. A machine stops, output falls, delivery commitments come under pressure, and the maintenance team has to respond before it has fully diagnosed the problem. For manufacturers operating heavy machinery, even a short interruption can create a chain reaction across the shop floor.
Predictive maintenance for heavy machinery helps manufacturers use equipment-condition data to identify potential problems earlier, plan maintenance more intelligently, and reduce avoidable interruptions. Instead of relying only on fixed service schedules or waiting for a breakdown, teams can use sensor readings, operating history, and maintenance records to make better-informed decisions about when equipment needs attention.
But predictive maintenance is not simply a matter of installing sensors or purchasing software. It requires selecting the right machines, collecting useful data, establishing meaningful alerts, and connecting those insights to maintenance action.
This guide explains how predictive maintenance works, which heavy machines can benefit, what data to monitor, how to implement a program, and how to evaluate whether it is delivering value.
What Is Predictive Maintenance for Heavy Machinery?
Predictive maintenance is a maintenance approach that uses observed equipment conditions and other relevant data to estimate when a machine or component may need attention.
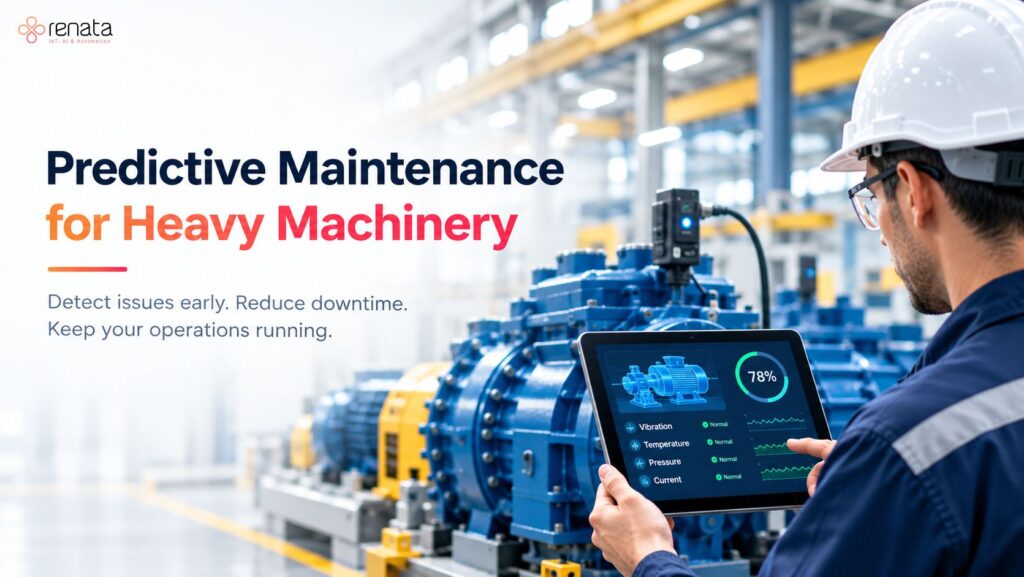
Depending on the application, the data may include vibration, temperature, pressure, current, operating hours, performance trends, fault history, and maintenance records. Analysis of these signals can help identify abnormal behaviour or developing faults before they result in an unexpected stoppage.
For example, a motor may continue running while its vibration gradually moves outside its normal operating pattern. A monitoring system can flag the change for investigation, allowing a maintenance engineer to check for possible misalignment, imbalance, bearing wear, or another cause.
The alert is an early warning—not automatic proof of a specific fault. A qualified person must interpret the data and determine the appropriate action.
The National Institute of Standards and Technology (NIST) describes predictive maintenance as maintenance initiated using predictions of failure based on observed data, including temperature, noise, and vibration.
Why Heavy Machinery Needs a Smarter Maintenance Strategy
Heavy machinery often operates under demanding conditions: high loads, long operating hours, dust, heat, vibration, and changing production requirements. These conditions can make equipment health difficult to assess through occasional inspections alone.
When maintenance teams have limited visibility into machine conditions, several challenges can arise:
- Unexpected downtime: Equipment may fail between scheduled inspections.
- Unnecessary maintenance: Components may be serviced or replaced before their actual condition requires it.
- Late fault detection: Small changes in machine behaviour may go unnoticed until performance deteriorates.
- Unplanned maintenance costs: Emergency repairs can require urgent labour, replacement parts, and production rescheduling.
- Limited visibility across sites: Teams responsible for multiple machines or plants may struggle to identify which assets need attention first.
- Incomplete maintenance records: When operating data and work orders are disconnected, identifying recurring faults becomes harder.
Predictive maintenance helps address these challenges by adding condition-based information to maintenance planning. It does not eliminate all failures, but it can give teams better evidence for deciding what to inspect, when to intervene, and which assets deserve priority.
Predictive vs. Preventive vs. Reactive Maintenance
Understanding the difference between maintenance approaches helps determine where predictive maintenance fits into a factory’s operating model.
Maintenance approach | When maintenance happens | Main advantage | Main limitation |
Reactive maintenance | After a failure or breakdown | Straightforward for low-criticality assets | Can lead to unexpected downtime |
Preventive maintenance | At planned time or usage intervals | Supports routine servicing and inspections | May service equipment too early or miss faults that develop between intervals |
Predictive maintenance | In response to condition data and evidence of developing faults | Supports more targeted maintenance planning | Depends on useful data, sound interpretation, and an effective response process |
These methods are not mutually exclusive. A practical maintenance program may use scheduled preventive maintenance for routine tasks, predictive monitoring for critical assets, and reactive repairs where the business impact of failure is low.
The US Department of Energy’s guidance on operations and maintenance approaches provides further context on preventive, predictive, and reliability-centred maintenance.
The goal is not to make every maintenance task predictive. It is to select the most suitable approach for each asset based on its criticality, failure patterns, operating environment, and the cost of monitoring.
How Predictive Maintenance Works
A predictive maintenance system combines equipment data, analysis, alerts, and maintenance action. The exact design depends on the machinery, available instrumentation, and the faults the team wants to identify.
1. Identify critical machines and failure modes
Start by identifying the machines whose failure would have the greatest impact on safety, production, product quality, energy use, or delivery commitments.
For each machine, list the important components and known failure modes. A motor, gearbox, pump, hydraulic system, and compressor may require different monitoring strategies.
This assessment helps answer two questions: which assets should be monitored first, and what kind of condition data is likely to be useful?
2. Collect equipment-condition data
Sensors and connected equipment can provide information about operating conditions. Depending on the asset, relevant signals may include:
- Vibration and changes in vibration patterns
- Bearing, motor, or gearbox temperature
- Pressure and flow
- Electrical current or power consumption
- Speed, load, and operating hours
- Machine cycle time and performance
- Alarm history and maintenance records
Not every machine needs every sensor. The data should be chosen according to the equipment’s failure modes and operating characteristics.
For existing machinery, the first step may be to assess available controller data and instrumentation before installing additional devices.
3. Establish normal operating patterns
A reading that is unusual for one machine may be normal for another. Load, speed, ambient temperature, product type, and operating mode can all affect sensor readings.
A useful monitoring setup establishes an appropriate baseline and accounts for normal operating variation. Teams can then investigate meaningful deviations rather than treating every fluctuation as a fault.
4. Analyse trends and identify anomalies
Monitoring software can compare incoming readings with configured thresholds, historical patterns, operating conditions, or analytical models.
Depending on the implementation, it may identify rising vibration, repeated temperature excursions, abnormal power consumption, or combinations of signals that warrant investigation.
More advanced analytics may help classify faults or estimate degradation. However, the reliability of those predictions depends on data quality, suitable models, operating context, and validation against actual equipment behaviour.
5. Generate alerts that support action
An alert should tell the maintenance team what needs attention, which asset is involved, when the abnormal condition occurred, and what evidence triggered the alert.
Where possible, alerts should include severity and supporting readings so that technicians can investigate efficiently. Alert thresholds should be reviewed over time to reduce nuisance alarms and missed warning signs.
6. Inspect, maintain, and learn
The final step is to turn monitoring information into a maintenance decision. A technician may inspect the equipment, confirm a fault, schedule a repair, or determine that the reading reflects a normal operating change.
Record the findings and compare them with the original alert. These records help the team refine thresholds, improve diagnosis, and evaluate whether the monitoring program is useful.
For further technical context, see NIST’s work on monitoring, diagnostics, and prognostics for manufacturing operations.
Which Heavy Machinery Can Benefit?
Predictive maintenance is most useful when equipment condition can be monitored meaningfully and when early intervention provides operational value.
Motors, gearboxes, and rotating equipment
Vibration, temperature, speed, and load data can help teams investigate possible imbalance, misalignment, bearing degradation, or unusual operating conditions. The appropriate measurements depend on the machine and the failure being assessed.
Pumps and hydraulic systems
Pressure, flow, temperature, motor current, and operating trends can help reveal changes in performance. A deviation may indicate a problem worth investigating, but it should be interpreted alongside process conditions and the manufacturer’s operating limits.
Industrial compressors
Monitoring pressure, temperature, operating cycles, and power consumption can help maintenance teams identify performance changes or repeated abnormal conditions. Additional signals may be appropriate depending on the compressor type and critical components.
CNC machines and production equipment
Machine status, cycle times, alarms, spindle conditions, and operating history can help teams investigate recurring stoppages and performance deterioration. Integration with existing controls may provide useful information before new sensors are installed.
Material-handling and heavy-duty equipment
Conveyors, lifting systems, and other material-handling assets may benefit from monitoring motors, gearboxes, bearings, operating cycles, and other critical components. Safety-related inspection and maintenance requirements must continue to be followed.
Multi-machine production lines
When a stoppage in one machine affects several downstream processes, machine-level monitoring can be combined with production information to prioritise maintenance around the wider operational impact.
The right starting point is not necessarily the largest machine. It is often the asset where failure risk, production impact, and the ability to detect a developing problem make monitoring worthwhile.
Key Benefits of Predictive Maintenance in Manufacturing
Reduce avoidable unplanned downtime
Early warning of abnormal equipment conditions gives teams an opportunity to investigate before a problem becomes a production-stopping failure. The actual reduction in downtime depends on the faults detected, the warning available, and whether the team can act in time.
Plan maintenance around production requirements
When an issue is detected early enough, maintenance may be scheduled during a planned stoppage or a suitable production window instead of being handled as an emergency.
Improve maintenance prioritisation
Condition information helps teams distinguish between assets that are operating normally and those that need investigation. This can support more informed decisions about labour, spare parts, and repair scheduling.
Support better equipment reliability
Repeated readings, alarm histories, inspection results, and repair records help maintenance teams recognise recurring patterns and investigate root causes.
Improve visibility across facilities
Where monitoring data from multiple assets or locations is available in a shared view, supervisors can review equipment status and emerging issues without relying entirely on manual updates from each site.
Make maintenance investment easier to evaluate
Tracking downtime, repair costs, false alarms, and confirmed faults helps a business assess whether its monitoring program is delivering measurable value. Benefits should be established from actual operating data rather than assumed in advance.
How to Implement Predictive Maintenance for Heavy Machinery
A phased rollout helps reduce complexity and makes it easier to learn before expanding the system.
Step 1: Build an asset criticality list
Document key machines, their production role, known failure history, maintenance costs, and the consequences of failure. Rank them by business impact and monitoring feasibility.
Step 2: Define the problem before choosing technology
Be specific about the outcome you want to improve. For example:
- Detect abnormal vibration on a critical motor.
- Identify repeated overheating in a gearbox.
- Investigate a recurring pump performance issue.
- Reduce unplanned stops on a bottleneck machine.
- Improve visibility into equipment condition across remote sites.
A clearly defined problem helps avoid collecting large amounts of data that do not support a maintenance decision.
Step 3: Check existing data and instrumentation
Review available PLC, SCADA, controller, sensor, and maintenance-system data. Determine whether existing readings are reliable and sufficiently frequent for the use case.
If additional instrumentation is needed, select it based on the target fault, machine characteristics, installation constraints, and operating environment.
Step 4: Choose the monitoring and analytics approach
Depending on the use case, the solution may use threshold-based alerts, trend analysis, condition-monitoring rules, statistical methods, or machine-learning models.
Do not assume that an AI model is necessary for every asset. A well-designed threshold or trend rule may be more appropriate for a clearly defined condition. More advanced analytics should be justified by the problem and validated against real equipment behaviour.
Step 5: Connect alerts to the maintenance workflow
Decide who receives alerts, how severity is assigned, how technicians acknowledge an issue, and how inspection findings are recorded.
A monitoring dashboard is not enough by itself. If alerts are ignored, unclear, or disconnected from work orders, the expected operational benefit may not materialise.
Step 6: Run a pilot on selected assets
Choose a manageable group of machines and establish a baseline before evaluating performance. Confirm that the data is dependable, alerts are actionable, and maintenance staff understand how to respond.
Include enough operating variation to understand how the system behaves under relevant conditions. The required pilot duration will depend on equipment use and how frequently the target fault conditions occur.
Step 7: Measure results before scaling
Compare results against the baseline. Review confirmed faults, warning lead time, unplanned downtime, maintenance costs, false alerts, and the time needed to investigate an alert.
Expand the program when the pilot demonstrates that the monitoring approach is technically useful and operationally justified.
KPIs to Measure Predictive Maintenance Performance
Track a small group of measures that connect equipment monitoring to business outcomes.
KPI | What it tells you |
Unplanned downtime hours | How much production time is lost to unexpected stops |
Mean time between failures (MTBF) | How frequently equipment failures occur over operating time |
Mean time to repair (MTTR) | How long repairs take on average, using a consistent definition |
Planned vs. unplanned maintenance | How the maintenance workload is distributed |
Alert precision | How often alerts correspond to a confirmed issue, according to an agreed definition |
Warning lead time | How much time is available between a useful warning and the relevant failure or intervention |
Maintenance cost per asset | How maintenance expenditure changes over time |
Production availability | How much of the required operating time equipment is available, using the site’s defined calculation |
Set definitions before measuring. For example, decide whether planned stops are excluded from downtime and how false alarms are counted. Consistent definitions make comparisons more meaningful.
A successful program should not be judged by the number of alerts generated. The important question is whether the information helps the team make better maintenance decisions and improve outcomes.
Common Predictive Maintenance Challenges—and How to Address Them
Poor or inconsistent sensor data
Missing readings, faulty sensors, inconsistent timestamps, and changing measurement conditions can lead to misleading results.
What to do: Validate instrumentation, establish data-quality checks, document operating conditions, and investigate missing or implausible values.
Too many alerts
Excessive notifications can cause alert fatigue and make important warnings easier to miss.
What to do: Review thresholds against actual operating behaviour, group related alerts where appropriate, and use clear severity and escalation rules.
Limited historical failure data
Some facilities may not have enough labelled failure examples to train or validate advanced prediction models.
What to do: Begin with a defined condition-monitoring use case, combine available engineering knowledge with observed data, and build a reliable history of alerts, inspections, and repairs.
Integration with existing systems
Older machinery may use different controllers, protocols, and data formats. Integration can require careful engineering.
What to do: Assess connectivity, compatibility, network requirements, and cybersecurity before implementation. Plan how the monitoring system will coexist with existing operational technology.
Difficulty proving return on investment
Equipment failures vary, and some faults may occur too infrequently to evaluate quickly.
What to do: Establish a baseline, record both costs and benefits, include implementation and ongoing maintenance costs, and avoid attributing every improvement to the monitoring system without evidence.
NIST’s research on evaluating condition-monitoring technologies highlights why the engineering and financial effects of these systems need to be evaluated in the context of the application.
How to Choose Predictive Maintenance Software for Heavy Machinery
Before selecting a platform, evaluate whether it can support your actual assets and maintenance workflows.
Use the following checklist when comparing solutions:
- Equipment compatibility: Can it work with the machines, controllers, and sensors used at your facility?
- Relevant monitoring parameters: Can it collect and display the data required for your priority failure modes?
- Actionable alerts: Can teams understand what triggered an alert and what needs investigation?
- Historical trends: Can users review readings, events, and equipment behaviour over time?
- Multi-site visibility: Can authorised teams view the relevant machines across facilities?
- Integration: Can the platform fit your existing operational systems and maintenance processes?
- Security and access control: Are data access, connectivity, user permissions, and remote access appropriately managed?
- Implementation support: Is there a practical plan for installation, configuration, validation, and ongoing support?
- Measurement of results: Can the system help your team assess whether alerts and maintenance actions are improving outcomes?
The best solution is not necessarily the one with the most features. It is the one that addresses your priority equipment risks, fits your operating environment, and supports a clear maintenance process.
If you are assessing options for connected equipment and factory operations, explore Renata’s predictive maintenance solutions. You can also review machine monitoring to understand the wider equipment-monitoring context.
Frequently Asked Questions
What is predictive maintenance for heavy machinery?
Predictive maintenance for heavy machinery uses equipment-condition data—such as vibration, temperature, pressure, operating history, and other relevant signals—to identify potential faults and support timely maintenance decisions.
Can predictive maintenance reduce machine downtime?
It can help reduce avoidable downtime when the system detects a developing issue early enough and the maintenance team can take appropriate action. Results depend on equipment, fault type, data quality, and implementation.
Which sensors are used for predictive maintenance?
Common options include vibration, temperature, pressure, flow, and electrical-current sensors. The correct selection depends on the machine, the component being monitored, and the failure mode being investigated.
Is predictive maintenance better than preventive maintenance?
Neither approach is best for every asset. Preventive maintenance remains useful for scheduled servicing and required inspections, while predictive maintenance adds condition-based evidence. Many facilities use both approaches together.
Does predictive maintenance require AI?
No. Some use cases can be handled with thresholds, trends, and established condition-monitoring rules. AI or machine-learning methods may be useful where the data and application justify them, but their performance must be validated.
How do manufacturers get started with predictive maintenance?
Start by identifying critical machines, reviewing failure history, selecting a specific maintenance problem, checking existing data, and running a pilot. Measure the results before extending the approach to more assets.
What should manufacturers look for in predictive maintenance software?
Look for equipment compatibility, useful condition data, actionable alerts, historical trends, appropriate integrations, security controls, implementation support, and clear ways to evaluate results.
Final Takeaway
Predictive maintenance for heavy machinery is most valuable when it turns equipment data into better maintenance decisions. Sensors and software can help reveal abnormal behaviour, but the operational benefit comes from combining reliable measurements with sound analysis, technician expertise, and a process for acting on alerts.
Manufacturers do not need to monitor every machine at once. Starting with a critical asset, a defined failure mode, and measurable objectives can help establish whether condition monitoring is worth expanding.
Planning to improve equipment visibility in your facility? Explore Renata’s predictive maintenance solutions or contact the Renata team to discuss your monitoring requirements.
Further reading and technical references
- NIST — Manufacturing Machinery Maintenance
- NIST — Monitoring, Diagnostics and Prognostics for Manufacturing Operations
- U.S. Department of Energy — Operations and Maintenance Challenges and Solutions
- NIST — Comprehensive Evaluations of Condition Monitoring-Based Technologies in Industrial Maintenance
Editorial note: Technical references are provided for further reading. Adapt implementation guidance to the equipment manufacturer’s instructions, site procedures, and applicable safety requirements.